Video Search Engine
A natural-language search system for finding driving events and multi-frame scenarios in large video datasets.
Overview
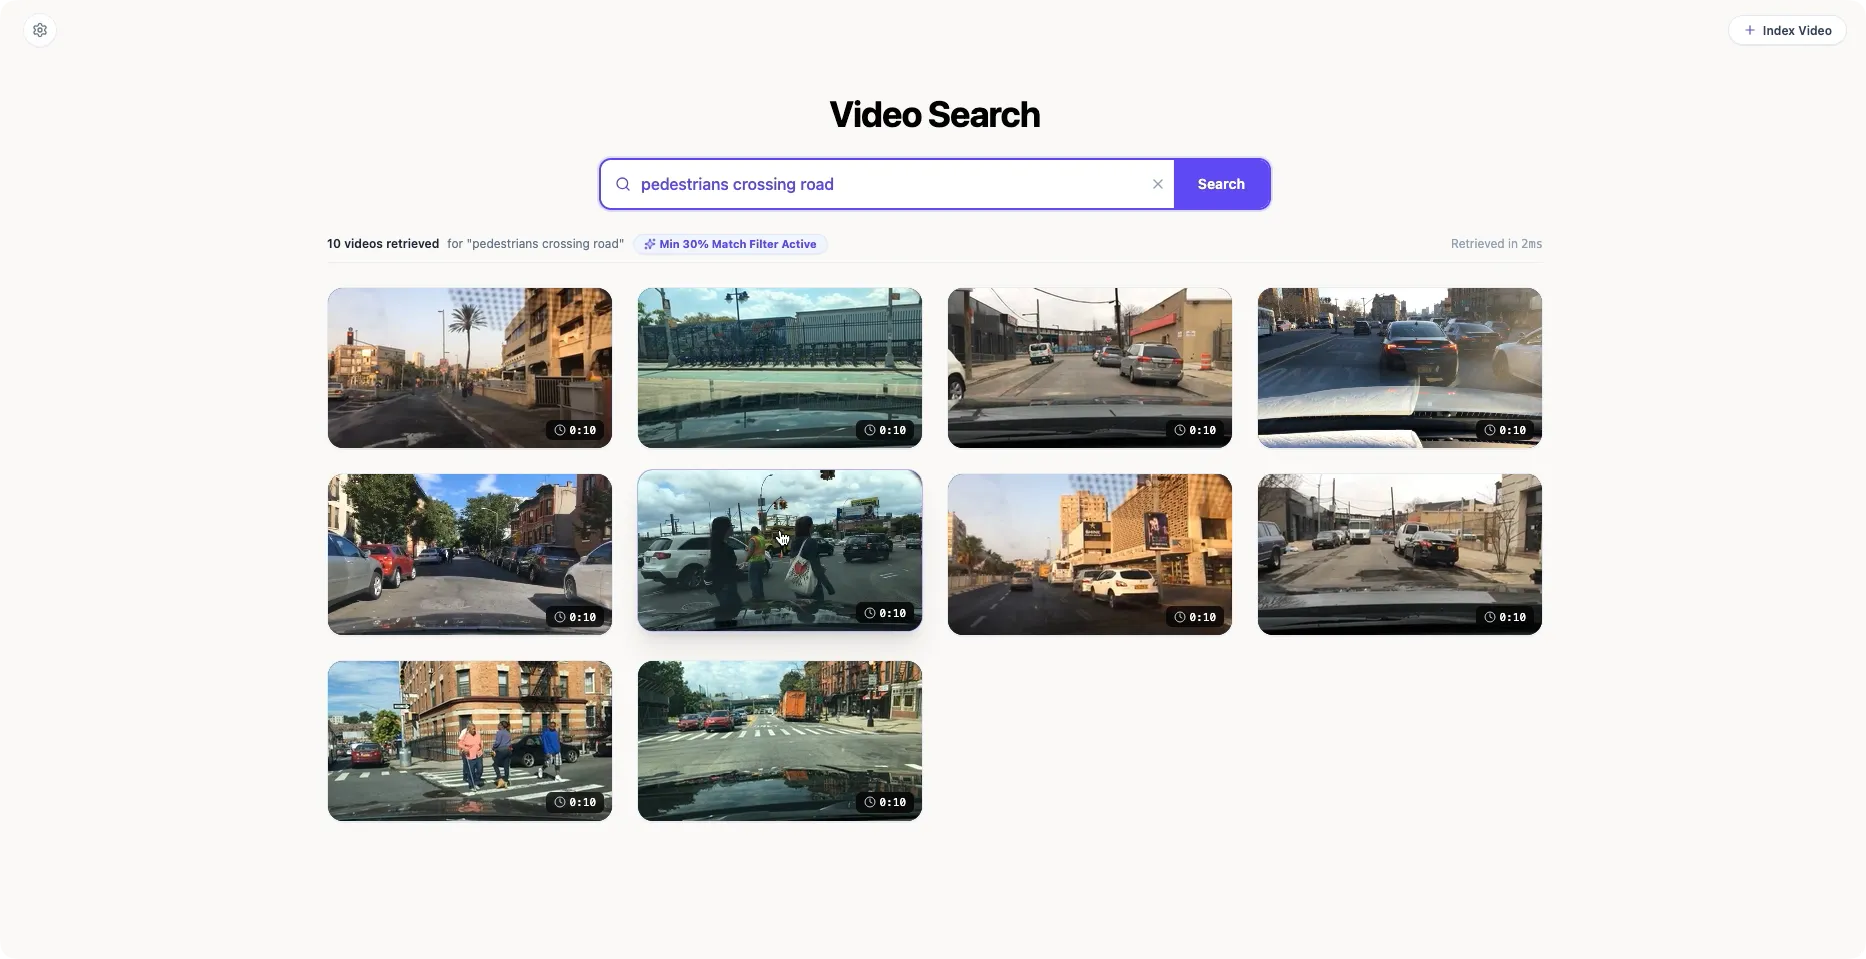
Autonomous-vehicle teams need to find specific events and multi-frame scenarios in large driving datasets, including rare edge cases that existing perception models may miss. Manually reviewing video makes it difficult to assemble targeted examples for model training and evaluation. As one of three engineers, I helped build a vision-language-model-powered search system that accepts natural-language descriptions of driving scenes.
My Contribution
The system processes on-road driving video and telemetry, extracts semantic descriptions of scenes, actors, objects, and events, and indexes them for retrieval. I contributed to planning the MVP roadmap and designing the overall architecture; built the data-processing pipeline; experimented with VLM prompts and semantic retrieval strategies; and developed the majority of the frontend, backend, search and retrieval, and deployment infrastructure using Docker and AWS.
Results
ML engineers could describe a scenario in natural language, retrieve matching driving clips, play the associated video, inspect metadata, and select examples for use in downstream dataset workflows. This greatly accelerated data acquisition from several weeks to a few hours, since our search engine did not rely on hand-engineered rules or custom scripts for searching for new scenarios.
The accompanying demo is a clean-room recreation of the core concept. It uses no proprietary Motional code, data, or internal interfaces.